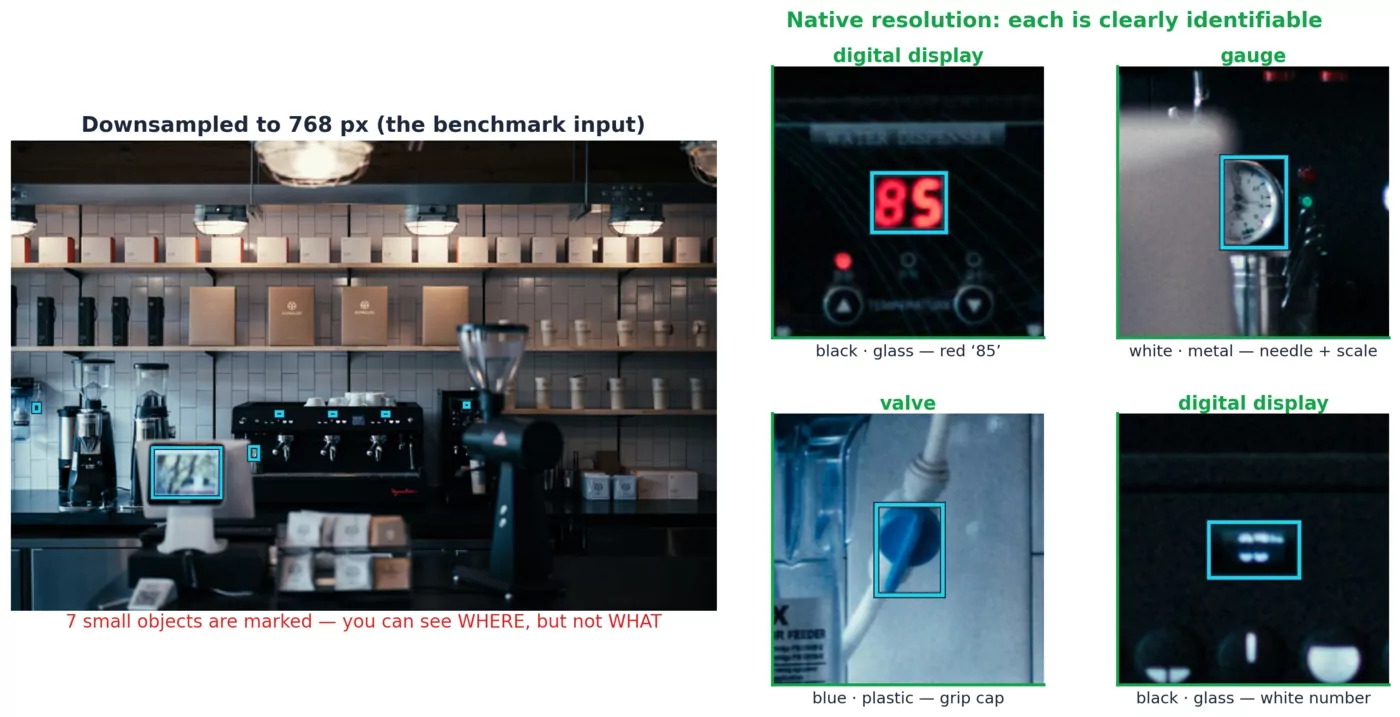
Open-vocabulary visual search
Exploring native-resolution strategies for finding small, open-vocabulary targets in high-resolution images.
Computer Vision Researcher & ML Engineer
I build and evaluate visual systems for autonomous driving and open-vocabulary search, focusing on reliability beyond familiar data.
Exploring native-resolution strategies for finding small, open-vocabulary targets in high-resolution images.
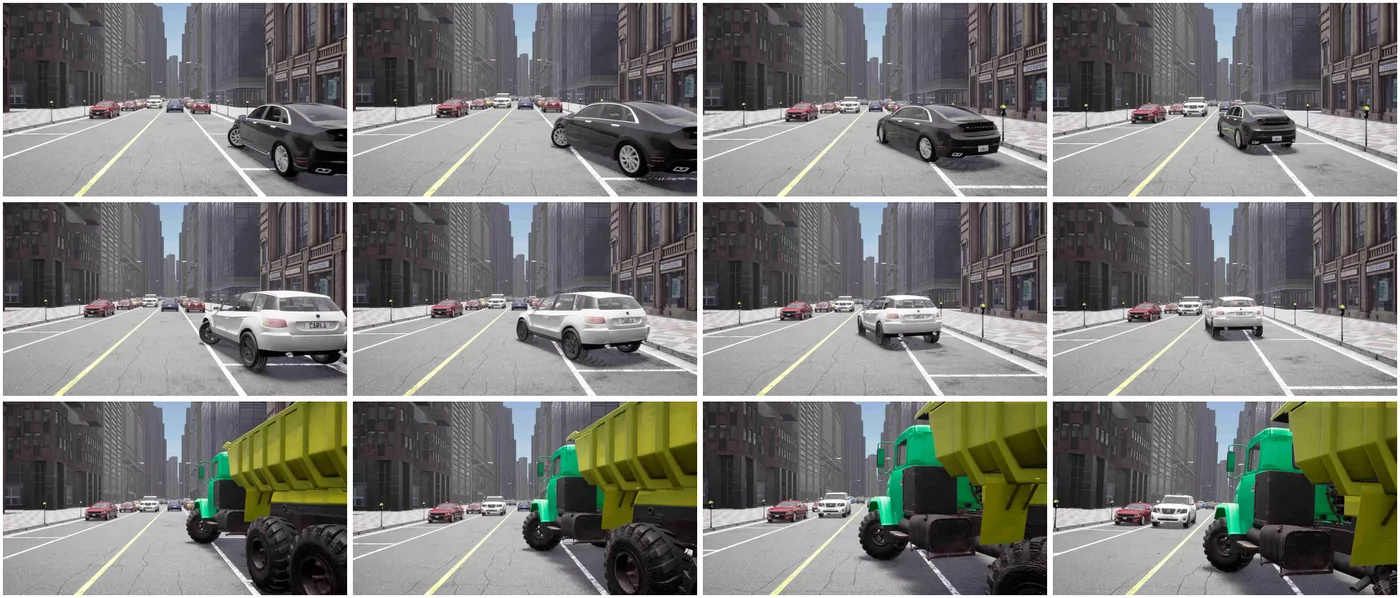
A closed-loop benchmark for how end-to-end driving systems respond to appearance and geometry shifts.
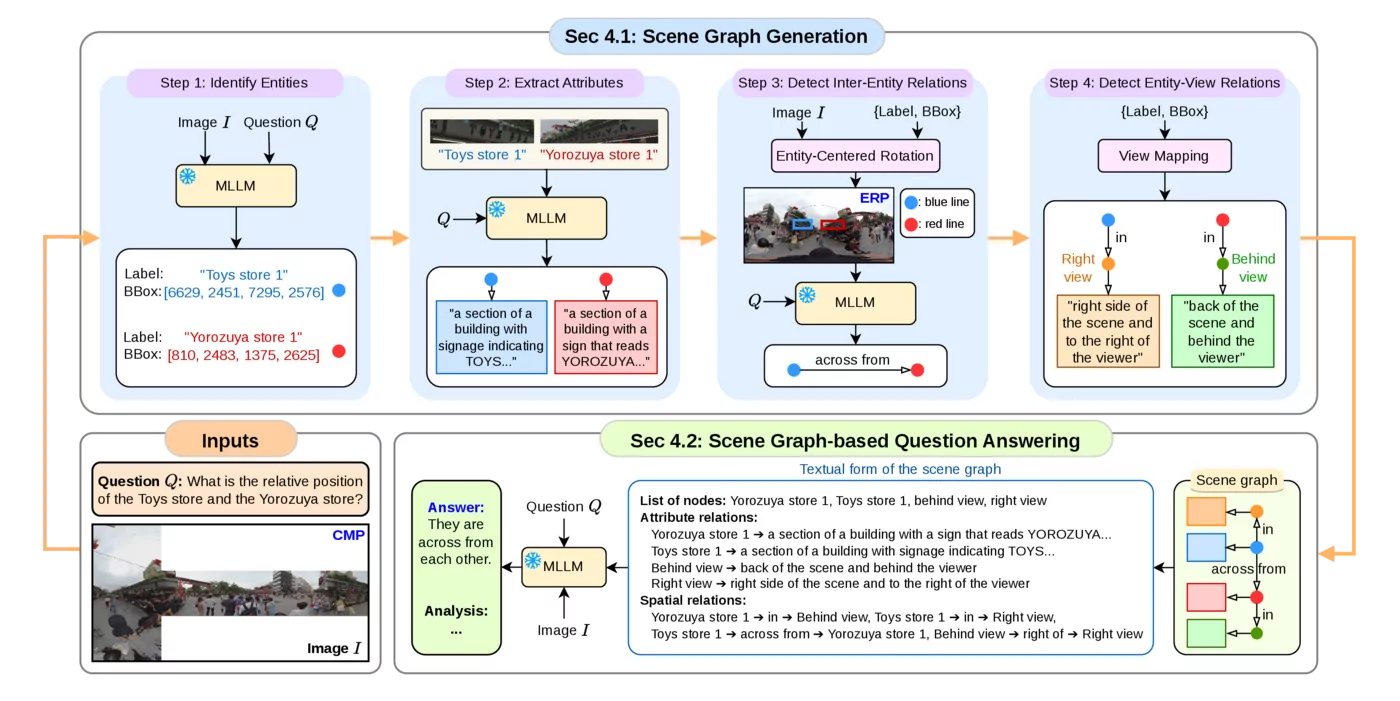
A panoramic VQA benchmark and training-free framework for structured reasoning over 360° images.
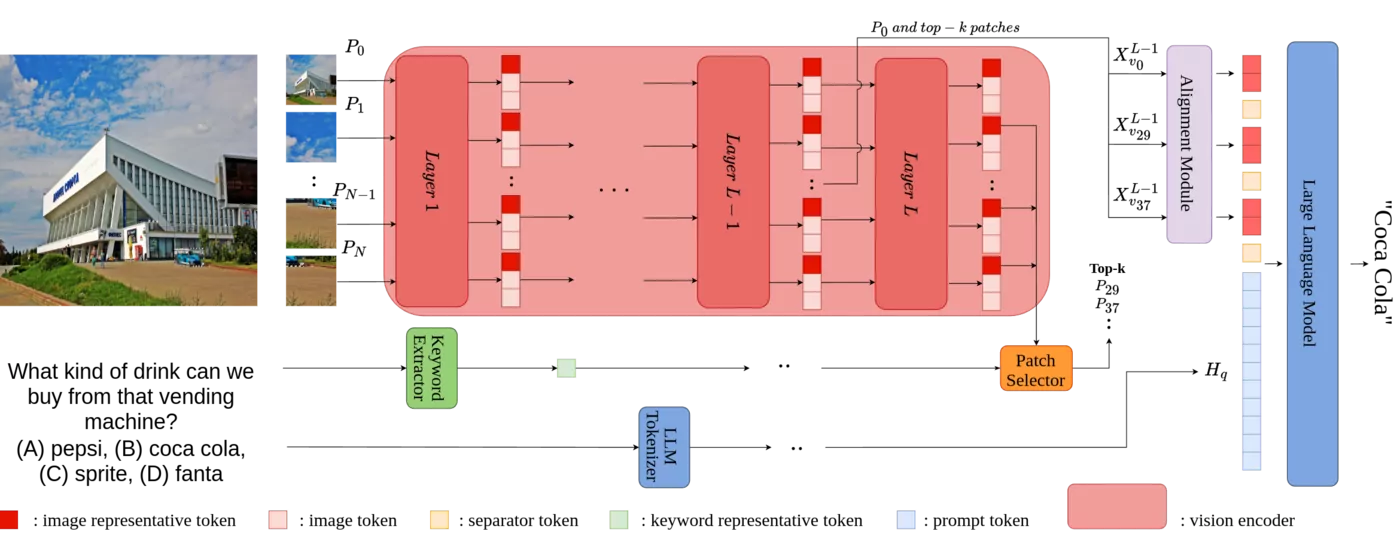
A training-free, plug-and-play method that helps vision-language models locate small details in high-resolution images.
Mercari, Inc.
Apr.–Jun. 2026
Okatani Computer Vision Lab, Tohoku University
Oct. 2024–Mar. 2026
Kisuitech
Jul.–Aug. 2024
Tohoku University
Oct. 2024–Sep. 2026
Tohoku University
Oct. 2020–Sep. 2024
Contributed model-loading and vision-processing features to Transformers and learning material for the Computer Vision Community Course.
Built a conversational wardrobe assistant that combines retrieval, recommendations, virtual try-on, and web search behind a tool-using agent.
Python · PyTorch · Hugging Face Transformers · OpenCV · CARLA · FastAPI · Docker